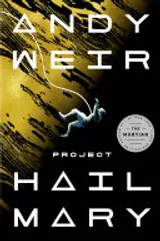
I wanted book covers on this site without manually finding every image and typing every author name. Google Books has enough data for that job, but I did not want the finished site to depend on Google loading images for every visitor.
The workflow
- Look up a book by ISBN with Google Books.
- Save the useful fields in JSON.
- Download the cover into
src/images/book-covers/. - Store its local path alongside the remote URL.
- Use Astro’s
Imagecomponent when a local cover exists. - Fall back to the remote URL or a placeholder when it does not.
The same data powers the favourite-books section on the homepage and the reading lists in older posts. One JSON shape means the components do not need to know where the information came from.
Why ISBNs
ISBN search is more reliable than title search. A request looks like this:
https://www.googleapis.com/books/v1/volumes?q=isbn:9780593135204From the response I keep the title, authors, and image URL.
{
  "isbn": "9780593135204",
  "title": "Project Hail Mary",
  "authors": "Andy Weir",
  "coverURL": "https://books.google.com/books/content?..."
}
The first version rendered coverURL directly. That was quick, but every visitor had to fetch several third-party images and Astro could not optimise them during the build.
Caching covers locally
The sync script downloads a cover only when needed and writes a localCover path back to the data. A local file gives the build stable input, better fallbacks, and image optimisation without a runtime dependency on a third party.
It also makes failures less dramatic. A missing cover can use a placeholder; it does not need to leave a broken image on the page.
Why this is enough
This is not a book database. It is a small convenience tool for a personal site. Google Books does the lookup, local files keep the final site fast, and JSON keeps the components boring. That is the right amount of system for it.